01
Input
The process starts with a description provided by the user through an interface designed to work on both desktop and mobile devices.
Project
A self-hosted image generation service built around local inference and an automated pipeline that transforms an initial idea into a request prepared for the generation system.
ai.vjml.es explores how to provide image generation through a simple interface while keeping processing within controlled infrastructure. The system automates request preparation before sending it to the local inference backend, separating the user experience from the complexity of the generation process.
The process starts with a description provided by the user through an interface designed to work on both desktop and mobile devices.
The request is automatically transformed into a structured description better suited to the generation process, reducing the need to manually construct complex prompts.
The pipeline organizes and refines the elements of the request before constructing the final input used by the generation backend.
The prepared request is processed by an inference backend running on self-hosted infrastructure and the result is returned to the interface as a generated image.
The same generation and exploration experience is available on desktop and mobile, including information about each generated image.
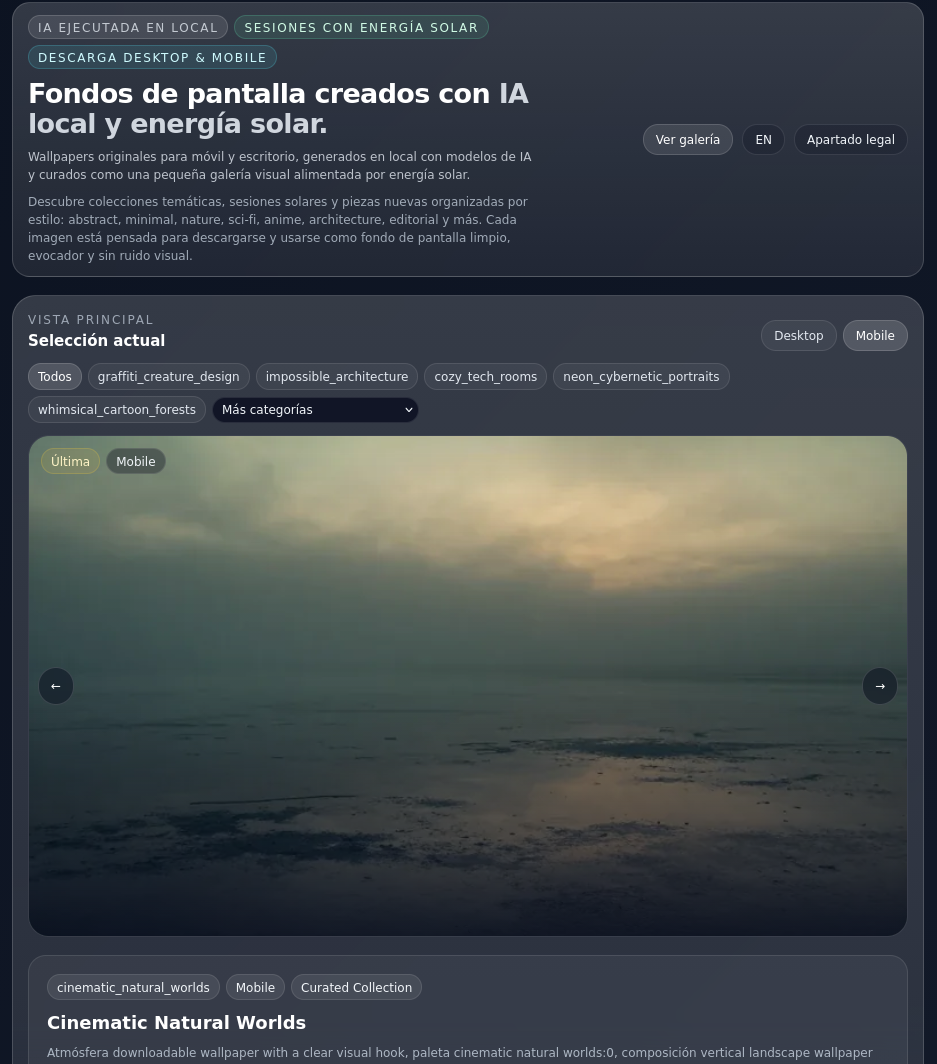
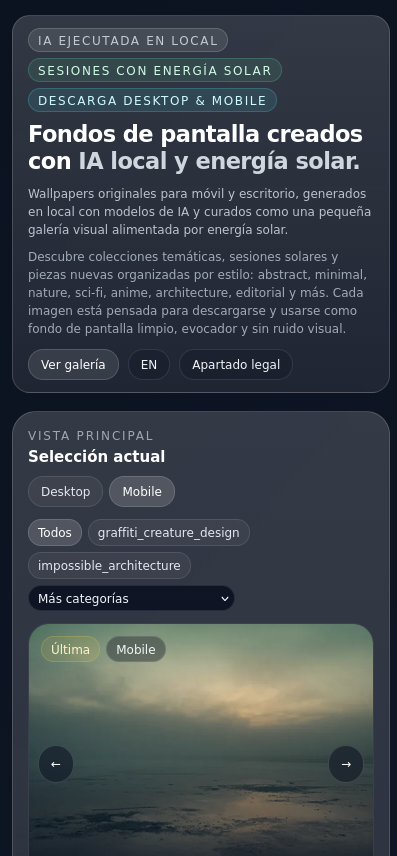
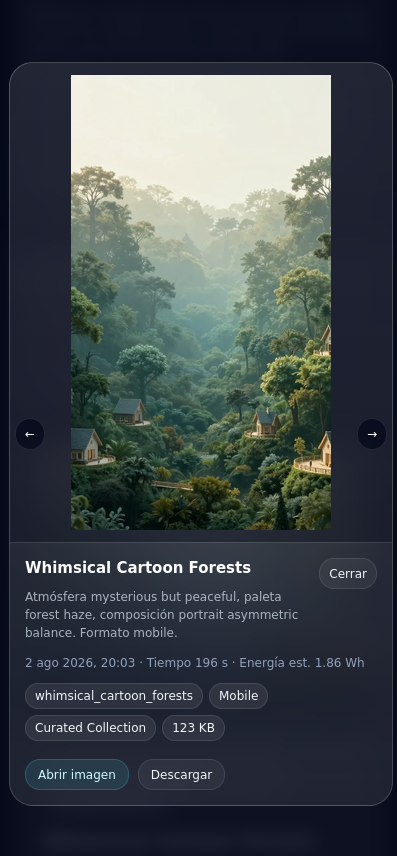
The application separates the public interface, request preparation and inference so that each part of the system can evolve independently.
The public interface where generation requests are created and results are presented, designed for both desktop and mobile.
The layer responsible for interpreting the request, structuring it and automatically constructing the input used to generate the image.
The service coordinates generation requests while keeping the Web application decoupled from the inference process.
Generation runs locally on controlled infrastructure without exposing implementation details of the inference backend.
The Web layer and inference workload can run on different systems, allowing each task to be assigned to the most appropriate node.
Component separation makes it possible to experiment with and evolve the pipeline without redesigning the public interface or coupling it to a particular inference implementation.
The current prompt pipeline is being refined to make better use of the information extracted from each request, improve composition and increase variation in generated results while keeping the user input simple.